


Provide MuleSoft MCD-Level-2 Dumps Updated Sep 10, 2023 With 62 QA's
Latest MCD-Level-2 Dumps for Success in Actual MuleSoft Certified
NEW QUESTION # 27
Which configurations are required for HTTP Listener to enable mTLS authentication?
- A. Set an appropriate keystore and truststore configuration for the listener
- B. Set an appropriate reconnection strategy and use persistent connections for the listener
- C. Set an appropriate truststore configuration and reconnection strategy for the listener
- D. Set an appropriate keystore configuration and use persistent connections for the listener
Answer: A
Explanation:
Explanation
To enable mTLS authentication for HTTP Listener, the developer needs to set an appropriate keystore and truststore configuration for the listener. The keystore contains the certificate and private key of the Mule application that are used to prove its identity to clients. The truststore contains the certificates of trusted clients that are allowed to access the Mule application. References:
https://docs.mulesoft.com/mule-runtime/4.3/tls-configuration#mutual-authentication
NEW QUESTION # 28
A Mule application contain two policies Policy A and Policy A has order1, and Policy B has order 2. Policy A Policy B, and a flow are defined by he configuration below.
When a HTTP request arrives at the Mule application's endpoint, what will be the execution order?
- A. B1, A1, F1, A2, B2
- B. A1, B1, F1, B2, A2
- C. F1, A1, B1, B2, A2
- D. F1, B1, A1, A2, B2
Answer: B
Explanation:
Explanation
Based on the configuration below, when a HTTP request arrives at the Mule application's endpoint, the execution order will be A1, B1, F1, B2, A2. This is because policies are executed before and after the API implementation flow according to their order attribute. Policy A has order 1, which means it is executed first before Policy B, which has order 2. The flow is executed after both policies are executed before the flow.
Then, Policy B is executed after the flow before Policy A is executed after the flow. References:
https://docs.mulesoft.com/api-manager/2.x/policies-policy-order
NEW QUESTION # 29
Which pattern can a web API use to notify its client of state changes as soon as they occur?
- A. Shared database trigger
- B. ETL data load
- C. Schedule Event Publisher
- D. HTTP Webhock
Answer: D
Explanation:
Explanation
A web API can use HTTP Webhook to notify its client of state changes as soon as they occur. A webhook is an HTTP callback that allows an API to send real-time notifications to another system or application when an event happens. The client registers a URL with the API where it wants to receive notifications, and then the API sends an HTTP request to that URL with information about the event. References:
https://docs.mulesoft.com/connectors/webhook/webhook-connector
NEW QUESTION # 30
An API has been developed and deployed to CloudHub Among the policies applied to this API is an allowlist of IP addresses. A developer wants to run a test in Anypoint Studio and does not want any policies applied because their workstation is not included in the allowlist.
What must the developer do in order to run this test locally without the policies applied?
- A. Pass in the runtime parameter ''-Danpow.platform.gatekeeper=disabled''
- B. Create a properties file specifically for local development and set the API instance ID to a value that is not used in API Manager
- C. Run the test as-s, with no changes because the Studio runtime will not attempt to connect to API Manager
- D. Deactivate the API in API Manager so the Autodiscovery element will not find the application when it runs in Studio
Answer: B
Explanation:
Explanation
To run a test locally without the policies applied, the developer should create a properties file specifically for local development and set the API instance ID to a value that is not used in API Manager. This way, the developer can use different configuration properties for different environments and avoid triggering API autodiscovery when running tests locally. API autodiscovery is a mechanism that associates an API implementation with its corresponding API specification and policies in API Manager based on its API instance ID. By setting this ID to a value that does not exist in API Manager, the developer can prevent API autodiscovery from finding and applying any policies to the local test. References:
https://docs.mulesoft.com/api-manager/2.x/api-auto-discovery-new-concept#configuring-api-autodiscovery
https://docs.mulesoft.com/mule-runtime/4.3/configuring-properties
NEW QUESTION # 31
A mule application exposes and API for creating payments. An Operations team wants to ensure that the Payment API is up and running at all times in production.
Which approach should be used to test that the payment API is working in production?
- A. Monitor the Payment API directly sending real customer payment data
- B. Create a health check endpoint that reuses the same port number and HTTP Listener configuration as the API itself
- C. Create a health check endpoint that listens on a separate port and uses a separate HTTP Listener configuration from the API
- D. Configure the application to send health data to an external system
Answer: C
Explanation:
Explanation
To test that the payment API is working in production, the developer should create a health check endpoint that listens on a separate port and uses a separate HTTP Listener configuration from the API. This way, the developer can isolate the health check endpoint from the API traffic and avoid affecting the performance or availability of the API. The health check endpoint should return a simple response that indicates the status of the API, such as OK or ERROR. References:
https://docs.mulesoft.com/api-functional-monitoring/afm-create-monitor#create-a-monitor
NEW QUESTION # 32
Which command is used to convert a JKS keystore to PKCS12?
- A. Keytool-importkeystore -srckeystore keystore jks-srcstoretype PKCS12 -destkeystore keystore.p12
-deststoretype JKS - B. Keytool-importkeystore -srckeystore keystore p12-srcstoretype JKS -destkeystore keystore.p12
-deststoretype PKCS12 - C. Keytool-importkeystore -srckeystore keystore jks-srcstoretype JKS -destkeystore keystore.p13
-deststoretype PKCS12 - D. Keytool-importkeystore -srckeystore keystore p12-srcstoretype PKCS12 -destkeystore keystore.jks
-deststoretype JKS
Answer: B
Explanation:
Explanation
To convert a JKS keystore to PKCS12, the developer needs to use the keytool-importkeystore command with the following options: -srckeystore keystore.jks -srcstoretype JKS -destkeystore keystore.p12 -deststoretype PKCS12. This command imports all entries from a source JKS keystore (keystore.jks) into a destination PKCS12 keystore (keystore.p12). References:
https://docs.oracle.com/en/java/javase/11/tools/keytool.html#GUID-5990A2E4-78E3-47B7-AE75-6D182625954
NEW QUESTION # 33
A heathcare customer wants to use hospital system data, which includes code that was developed using legacy tools and methods. The customer has created reusable Java libraries in order to read the data from the system.
What is the most effective way to develop an API retrieve the data from the hospital system?
- A. Include the libraries writes deploying the code into the runtime
- B. Install libraries in a local repository and refer to it in the pm.xml file
- C. Refer to JAR files in the code
- D. Create the Java code in your project and invoice the data from the code
Answer: B
Explanation:
Explanation
To develop an API that retrieves data from a hospital system using reusable Java libraries, the developer should install libraries in a local repository and refer to it in the pom.xml file. This way, the developer can use Maven to manage dependencies and invoke Java code from Mule applications using Java Module operations.
References:
https://docs.mulesoft.com/mule-runtime/4.3/java-module-reference#add-the-java-module-to-your-project
https://docs.mulesoft.com/mule-runtime/4.3/java-module-reference#invoke-java-code
NEW QUESTION # 34
A Mule application includes a subflow containing a Scatter.Gather scope. Within each log of the Scatter.Gatter. an HTTP connector calls a PUT endpoint to modify records in different upstream system. The subflow is called inside an Unit successful scope to retry if a transitory exception is raised.
A technical spike is being performed to increase reliability of the Mule application.
Which steps should be performed within the Mule flow above the ensure idempontent behavior?
- A. Ensure an error-handling flow performs corrective actions to roll back all changes if any leg of the Scatter-Gather fails
- B. Change the PUT requests inside the Scatter-Gather to POST requests
- C. None, the flow already exhibits idempotent behavior
- D. Remove the Put requests from the Scatter-Getter and perform them sequentially
Answer: A
Explanation:
Explanation
To ensure idempotent behavior within a Mule flow that contains a subflow with a Scatter-Gather scope, the developer should ensure an error-handling flow performs corrective actions to roll back all changes if any leg of the Scatter-Gather fails. Idempotency means that multiple identical requests have the same effect as a single request. Therefore, if one of the HTTP requests inside the Scatter-Gather fails, the error-handling flow should undo any changes made by other successful requests to ensure consistency and avoid partial updates.
References: https://docs.mulesoft.com/mule-runtime/4.3/scatter-gather-concept
https://docs.mulesoft.com/mule-runtime/4.3/error-handling
NEW QUESTION # 35
A Mule application need to invoice an API hosted by an external system to initiate a process. The external API takes anywhere between one minute and 24 hours to compute its process.
Which implementation should be used to get response data from the external API after it completes processing?
- A. Expose an HTTP callback API in Mule and register it with the external system
- B. Use an HTTP Connector to invoke the API and wait for a response
- C. Use an HTTP Connector inside Async scope to invoice the API and wait for a response
- D. Use a Scheduler to check for a response every minute
Answer: A
Explanation:
Explanation
To get response data from the external API after it completes processing, the developer should expose an HTTP callback API in Mule and register it with the external system. This way, the external API can invoke the callback API with the response data when it is ready, instead of making the Mule application wait for a long time or poll for a response repeatedly. References:
https://docs.mulesoft.com/mule-runtime/4.3/http-listener-ref#callback
NEW QUESTION # 36
Which plugin or dependency is required to unit test modules created with XML SDK?
- A. Junit
- B. MUnit Maven plugin
- C. MUnit Extensions Maven plugin
- D. XMLUnit
Answer: C
Explanation:
Explanation
To unit test modules created with XML SDK, the developer needs to use the MUnit Extensions Maven plugin.
This plugin allows testing XML SDK modules using MUnit by adding a dependency to the module under test and using a custom processor tag to invoke it. References:
https://docs.mulesoft.com/mule-sdk/1.1/xml-sdk#testing
NEW QUESTION # 37
In a Mule project, Flow-1 contains a flow-ref to Flow-2 depends on data from Flow-1 to execute successfully.
Which action ensures the test suites and test cases written for Flow-1 and Flow-2 will execute successfully?
- A. Use 'After Test Case' to produce the data needed from Flow-1 test cases to pass to Flow-2 test cases
- B. Use ''Set Event to pass the input that is needed, and keep the test cases for Flow-1 and Flow-2 independent
- C. Use ''Before Test Case'' To collect data from Flow-1 test cases before running Flow-2 test cases
- D. Chain together the test suites and test cases for Flow-1 and Flow-2
Answer: B
Explanation:
Explanation
To ensure the test suites and test cases written for Flow-1 and Flow-2 will execute successfully, the developer should use a Set Event processor to pass the input that is needed by Flow-2, and keep the test cases for Flow-1 and Flow-2 independent. This way, the developer can isolate the testing of each flow and avoid coupling them together. References: https://docs.mulesoft.com/munit/2.3/munit-test-flow
NEW QUESTION # 38
Which statement is true when using XML SDK for creating custom message processors?
- A. All operations are public
- B. Operations can be reused in recursive calls
- C. Properties are fields defined by an end user of the XML SDK component and serve as a global configuration for the entire Mule project in which they are used
- D. An XML SDK provides both inbound and outbound operations
Answer: A
Explanation:
Explanation
When using XML SDK for creating custom message processors, all operations are public by default and can be used by any Mule application that imports them. There is no way to make an operation private or protected in XML SDK. References: https://docs.mulesoft.com/mule-sdk/1.1/xml-sdk#operations
NEW QUESTION # 39
Refer to the exhibit.
A Mute Object Store is configured with an entry TTL of one second and an expiration interval of 30 seconds.
What is the result of the flow if processing between os'store and os:retrieve takes 10 seconds?
- A. nullPayload
- B. originalPayload
- C. testPayload
- D. OS:KEY_NOT_FOUND
Answer: A
Explanation:
Explanation
The result of the flow is nullPayload if processing between os:store and os:retrieve takes 10 seconds. This is because the entry TTL of the object store is one second, which means that any stored value expires after one second and is removed from the object store. The expiration interval of 30 seconds only determines how often the object store checks for expired values, but it does not affect the TTL. Therefore, when os:retrieve tries to get the value after 10 seconds, it returns nullPayload because the value has already expired and been removed.
References: https://docs.mulesoft.com/object-store/osv2-faq#how-does-the-time-to-live-work
NEW QUESTION # 40
A company with MuleSoft Titanium develops a Salesforce System API using MuleSoft out-of-the-box Salesforce Connector and deploys the API to CloudHub.
Which steps provide the average number of requests and average response time of the Salesforce Connector?
- A. Access Anypoint Monitoring built-in dashboard.
Select a resource.
Locate the information under Log Manager < Raw Data. - B. Change the API Implementation to capture the information in the log.
Retrieve the information from the log file. - C. Access Anypoint Monitoring's built-in dashboard
Seclect a resource.
Create a custom dashboard to retrieve the information. - D. Access Anypoint Monitoring's built-in dashboard. Select a resource.
Locate the information under the Connectors tab.
Answer: D
Explanation:
Explanation
To get the average number of requests and average response time of the Salesforce Connector, the developer should access Anypoint Monitoring's built-in dashboard, select a resource (such as an application or an API), and locate the information under the Connectors tab. The Connectors tab shows metrics for each connector used by the resource, such as average requests per minute, average response time, and failures. References:
https://docs.mulesoft.com/monitoring/built-in-dashboard-reference
NEW QUESTION # 41
A custom policy needs to be developed to intercept all cutbound HTTP requests made by Mule applications.
Which XML element must be used to intercept outbound HTTP requests?
- A. htt-policy:operation
- B. It is not possible to intercept outgoing HTTP requests, only inbound requests
- C. http-policy:processor
- D. http-policy:source
Answer: C
Explanation:
Explanation
The http-policy:processor element is used to intercept outbound HTTP requests made by Mule applications. It allows customizing the request before it is sent to the target API and modifying the response after it is received from the target API. References:
https://docs.mulesoft.com/api-manager/2.x/policy-mule4-custom-policy#policy-xml-file
NEW QUESTION # 42
A developer deploys an API to CloudHub and applies an OAuth policy on API Manager. During testing, the API response is slow, so the developer reconfigures the API so that the out-of-the-box HTTP Caching policy is applied first, and the OAuth API policy is applied second.
What will happen when an HTTP request is received?
- A. In case of a cache hit, both the OAuth and HTTP Caching policies are evaluated; then the cached response is returned to the caller
- B. In case of a cache miss, both the OAuth and HTTP Caching policies are evaluated; then the API retrieves the data from the API implementation, and the policy does not store the data in Object Store
- C. In case of a cache it, only the HTTP Caching policy is evaluating; then the cached response is returned to the caller
- D. In case of a cache miss, only the HTTP Caching policy is evaluated; then the API retrieves the data from the API implementation, and the policy stores the data to be cached in Object Store
Answer: C
Explanation:
Explanation
When an HTTP request is received and the HTTP Caching policy is applied first, it checks if there is a cached response for that request in Object Store. If there is a cache hit, meaning that a valid cached response exists, then only the HTTP Caching policy is evaluated and the cached response is returned to the caller without invoking the OAuth policy or the API implementation. If there is a cache miss, meaning that no valid cached response exists, then both the HTTP Caching policy and the OAuth policy are evaluated before invoking the API implementation. References:
https://docs.mulesoft.com/api-manager/2.x/http-caching-policy#policy-ordering
NEW QUESTION # 43
The HTTP Request operation raises an HTTP CONNECTIVITY error.
Which HTTP status code and body are returned to the web client?
- A. HTTP Status Code:200.
Body 'Error in processing your request - B. HTTP Status Code:500.
Body 'Error in processing your request - C. HTTP Status Code:500.
Body 'The HTTP CONNECTIVITY Error description - D. HTTP Status Code:500.
Body 'Error in processing your request
Answer: B
Explanation:
Explanation
When the HTTP Request operation raises an HTTP CONNECTIVITY error, it triggers an on-error-continue handler that sets a payload with 'Error in processing your request'. Since no status code is explicitly set in this handler, it defaults to 500 (INTERNAL SERVER ERROR). Therefore, the web client receives an HTTP response with status code 500 and body 'Error in processing your request'. References:
https://docs.mulesoft.com/mule-runtime/4.3/error-handling#on-error-continue
NEW QUESTION # 44
Refer to the exhibit.
What action must be performed to log all the errors raised by the VM Connector?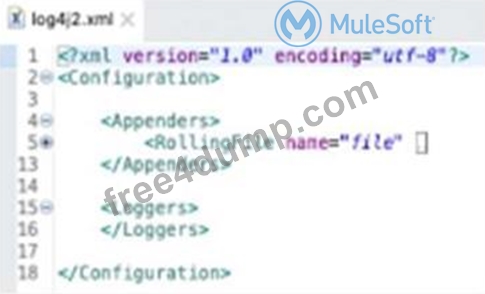
- A. Add <AsyncLOgger name='orgroute.extensions vm' level=ERROR'I> inside the Logger tag
- B. Configure <Logger level-'ERROR'/> inside the VM Connector configuration
- C. Add <AsyncLOgger name='orgroute.extensions vm' level=ERROR'/> inside the Appenders tag
- D. Nothing, as error-level events are automatically logged
Answer: C
Explanation:
Explanation
To log all the errors raised by the VM Connector, the developer needs to add an async logger with the name
'org.mule.extension.vm' and the level 'ERROR' inside the appenders tag of the log4j2.xml file. This will enable logging all error-level events generated by the VM Connector to the console appender. References:
https://docs.mulesoft.com/mule-runtime/4.3/logging-in-mule#configuring-custom-logging-settings
NEW QUESTION # 45
A Mule application deployed to multiple Cloudhub 2.0 replicas needs to temporarily persist large files over
10MB between flow executions, and routinely needs to query whether the file data exists on separate executions.
How can this be achieved?
- A. Store the key and full contents of the file in an Object Store
- B. Store the contents of the file on separate storage, and store the key and location of the file Object using Object Store v2
- C. Store the key and full contents of the file, caching the filename and location between requests
- D. Use an in-memory Object Store
Answer: B
Explanation:
Explanation
To temporarily persist large files over 10MB between flow executions, and routinely query whether the file data exists on separate executions, the developer should store the contents of the file on separate storage, and store the key and location of the file object using Object Store v2. This way, the developer can avoid storing large files in memory or exceeding the size limit of Object Store v2 (10MB per object). The developer can also use Object Store v2 operations to query, retrieve, or delete the file object by its key. References:
https://docs.mulesoft.com/object-store/osv2-faq#can-i-store-files-in-object-store-v2
NEW QUESTION # 46
When registering a client application with an existing API instance or API Group instance, what is required to manually approve or reject request access?
- A. To configure the SLA tier for the application and have the role of Organization Administrator, API Manager Environment Administrator, or the Manage Contacts permission
- B. To only have Exchange Administrator permission
- C. To configure the SLA tier for the application and have the Exchange Administrator permission
- D. To configure the SLA tier for the application
Answer: A
Explanation:
Explanation
To manually approve or reject request access when registering a client application with an existing API instance or API Group instance, it is required to configure the SLA tier for the application and have one of the following roles or permissions: Organization Administrator, API Manager Environment Administrator, or Manage Contracts permission. These roles or permissions allow managing client applications and contracts in API Manager. References:
https://docs.mulesoft.com/api-manager/2.x/client-applications#managing-client-applications-and-contracts
NEW QUESTION # 47
A Mule application deployed to a standardalone Mule runtime uses VM queues to publish messages to be consumed asynchronously by another flow.
In the case of a system failure, what will happen to in-flight messages in the VM queues that have been consumed?
- A. For nay type of queue, the message will be processed after the system comes online
- B. For any type of queue, the message will be lost
- C. For persistent queues, the message will be processed after the system comes online
- D. For transient queues, the message will be processed after the system comes online
Answer: C
Explanation:
Explanation
In case of a system failure, in-flight messages in persistent VM queues that have been consumed will be processed after the system comes online. This is because persistent VM queues store messages on disk and guarantee delivery even if there is a system crash or restart. Therefore, any in-flight messages that have been consumed but not processed will be recovered from disk and processed when the system is back online.
References: https://docs.mulesoft.com/mule-runtime/4.3/vm-connector#persistent-queues
NEW QUESTION # 48
Which properties are mandatory on the HTTP Connector configuration in order to use the OAuth 2.0 Authorization Code grant type for authentication?
- A. External callback URL, access token URL, client ID response access token
- B. Token URL, authorization URL, client ID, client secret local callback URL
- C. External callback URL, access token URL, client ID, response refresh token
- D. External callback URL, access token URL, local authorization URL, authorization URL, client ID, client secret
Answer: B
Explanation:
Explanation
To use the OAuth 2.0 Authorization Code grant type for authentication, the HTTP Connector configuration requires the following properties: token URL, authorization URL, client ID, client secret, and local callback URL. The token URL is the endpoint of the authorization server that provides access tokens. The authorization URL is the endpoint of the authorization server that initiates the user consent flow. The client ID and client secret are the credentials of the Mule application registered with the authorization server. The local callback URL is the endpoint of the Mule application that receives the authorization code from the authorization server.
References: https://docs.mulesoft.com/http-connector/1.6/http-authentication#oauth-2-0
NEW QUESTION # 49
An API has been built to enable scheduling email provider. The front-end system does very little data entry validation, and problems have started to appear in the email that go to patients. A validate-customer'' flow is added validate the data.
What is he expected behavior of the 'validate-customer'' flow?
- A. If all of the values are invalid the last validation error is
raised:SCHEDULE:INVALID_CUSTOMER_NAME - B. If only the email address Is invalid a VALIDATION.INVALID_EMAIL error is raised
- C. If the email address is invalid, processing continues to see if the appointment data and customer name are also invalid
- D. If the appointment date and customer name are invalid, a
SCHEDULE:INVALID_APPOINTMENT_DATE error is raised
Answer: B
Explanation:
Explanation
The validate-customer flow uses an until-successful scope to validate each field of the customer data. The until-successful scope executes its processors until they succeed or exhausts the maximum number of retries.
If any processor fails, it raises an error and stops executing the remaining processors. Therefore, if only the email address is invalid, a VALIDATION.INVALID_EMAIL error is raised and the validation of appointment date and customer name is skipped. References:
https://docs.mulesoft.com/mule-runtime/4.3/until-successful-scope
NEW QUESTION # 50
A Mule application uses API autodiscovery to access and enforce policies for a RESTful implementation.
- A. Northing because flowRef is an optional attribute which can be passed runtime
- B. Any of the APIkit generate implement flows
- C. The name of the flow that has HTTP listener to receive all incoming RESTful operation requests
- D. The name of the flow that has APlkit Console to receive all incoming RESTful operation requests.
Answer: C
Explanation:
Explanation
To use API autodiscovery to access and enforce policies for a RESTful implementation, flowRef must be set to the name of the flow that has HTTP listener to receive all incoming RESTful operation requests. This way, API autodiscovery can identify the API implementation and associate it with the corresponding API specification and policies in API Manager. The flow that has HTTP listener is usually the main flow that contains the APIKit Router. References:
https://docs.mulesoft.com/api-manager/2.x/api-auto-discovery-new-concept#flowref
NEW QUESTION # 51
Refer to the exhibit.
When creating a new project, which API implementation allows for selecting the correct API version and scaffolding the flows from the API specification?
- A. Generate a local RAML from anypoint Studio
- B. Download RAML from Design Center'
- C. Import a published API
- D. Import RAML from local file
Answer: C
Explanation:
Explanation
To create a new project that selects the correct API version and scaffolds the flows from the API specification, the developer should import a published API. This option allows importing an API specification that has been published to Anypoint Exchange or Design Center, and selecting a specific version of that API specification.
The developer can also choose to scaffold flows based on that API specification. References:
https://docs.mulesoft.com/apikit/4.x/apikit-4-new-project-task
NEW QUESTION # 52
......
Changing the Concept of MCD-Level-2 Exam Preparation 2023: https://www.free4dump.com/MCD-Level-2-braindumps-torrent.html